Use-Case and Category Recommendations
Category overview
Elo is the primary measure of competitive standing. The 1–10 averages help explain the model's behavior within each category; they should not be used to rank it against other models.
1. Short-text signs and cover concepts
Recommended with proofreading. This is the model's strongest competitive category.
The Open 24/7 neon storefront combines accurate text with convincing installation details and earns 9/10 overall. The urban STOP sign earns 8/10, preserving readable typography, sign geometry, and foreground construction.
Use it for:
- Short signs and prominent slogans.
- Early book-cover or poster compositions.
- Product concepts where text occupies a clear, uncluttered region.
Avoid treating generated editorial copy as finished. The movie poster shows that a successful headline can coexist with unusable credits. For production, add or replace supporting text in a layout tool.
2. Logos, promotional graphics, and interface assets
Good for selected single-asset concepts; weaker for coordinated systems.
The Evergreen Brew leaf logo scores 9/10 and ranks first in its supplied 13-image comparison group. It succeeds through restraint: one leaf, accurate wording, clear spacing, and no unnecessary additions. The Evergreen Brew logo image is the clearest example of the model meeting a compact design brief directly.
By contrast:
Use it to explore a logo direction or decorative visual. Avoid assuming complete icon coverage, seamless repeats, accurate offers, or editable vector construction. The cyberpunk wallpaper is a stronger abstract result at 8/10, but widescreen suitability is untested because the benchmark mandates square images.
3. Anime, comics, and action illustration
Recommended for spectacle-driven concepts.
The 90s anime space battle earns 9/10, with strong diagonals, detailed ships, layered depth, and controlled effects. The halftone superhero flight earns 8/10, supported by an imposing silhouette and richly developed city.
These are favorable requests because composition, lighting, and surface detail carry much of the appeal.
Check focal anatomy carefully. The otherwise appealing cat-and-dog adventure drops to 5/10 overall because the puppy appears to have an extra paw. The ramen-counter scene also struggles where hand, utensil, and noodles meet.
4. Warm, hand-drawn fantasy scenes
Recommended when the goal is appealing fantasy illustration rather than an exact film-style match.
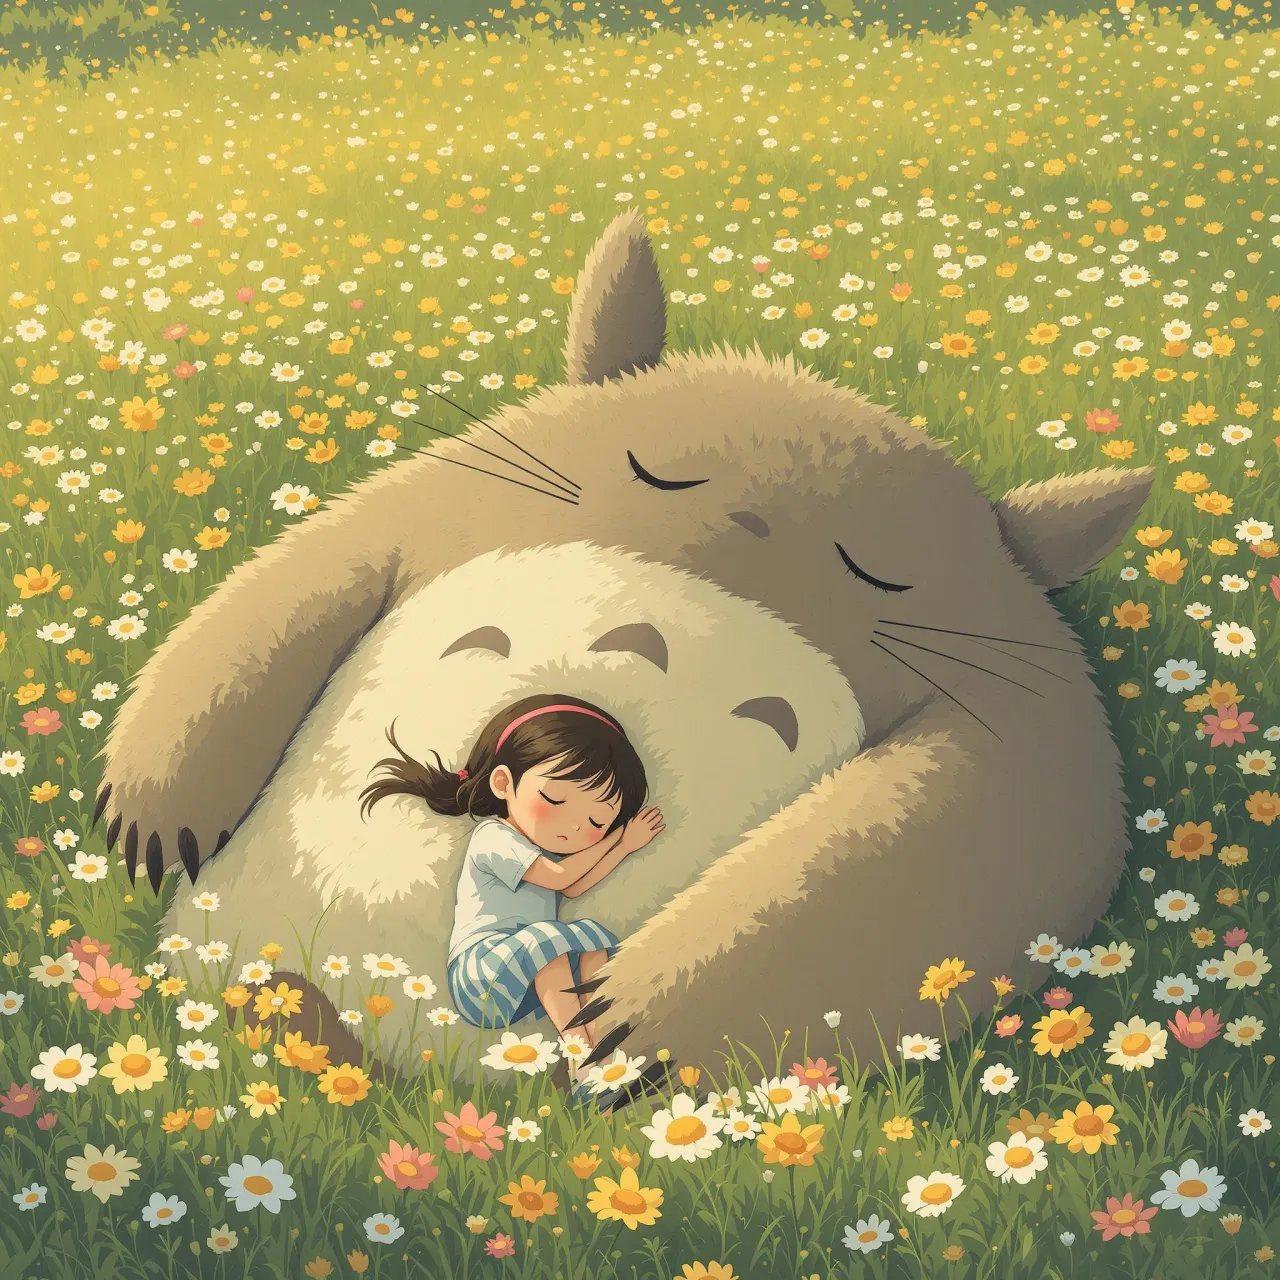
The girl and giant creature napping reaches 9/10, combining tenderness, protective posing, coordinated colors, and rich fur and flowers. The enchanted bathhouse reaches 8/10, with strong architectural depth and warm-cool lighting.
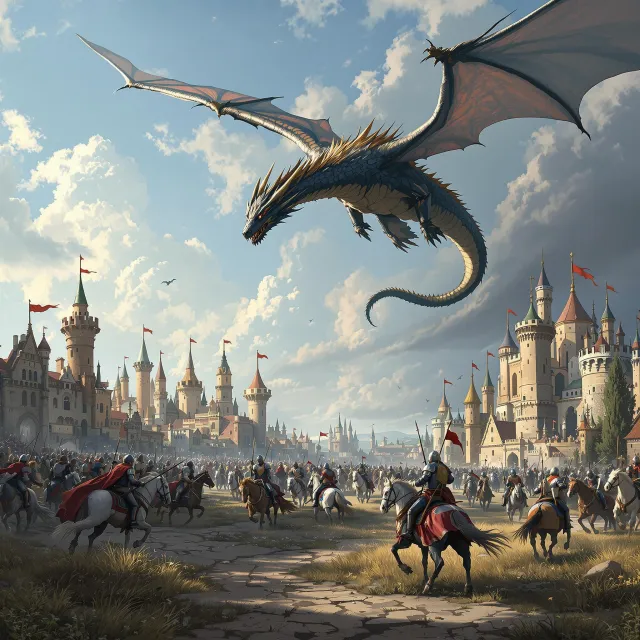
However, the evaluation repeatedly describes a shift toward crisp color blocking, glossy volume, or ornamental detail rather than restrained painted animation. The coastal witch flight has 9/10 artistic merit but only 6/10 prompt adherence.
Also distinguish magical atmosphere from magical action: the breakfast kitchen supplies steam and sparkles, but no implement clearly cooks through magic.
5. Markets, crowds, and multi-subject scenes
Use for environmental storytelling; simplify tightly specified activity lists.
The bustling market earns 8/10 overall and 10/10 adherence, successfully communicating many people and varied merchandise. The astronaut and diver playing chess also earns 8/10, with strong material separation, though precise glove-to-piece contact remains uncertain.
The model is less dependable when every participant needs a distinct role. The family cooking scene and classroom activities both score 5/10. Requested secondary subjects can disappear entirely: the reef exploration scene omits the shipwreck and shows only one diver.
For important deliverables, reduce the number of simultaneous actions and make the central interaction visually dominant.
6. Hands, gestures, and action anatomy
Use only with close review; avoid anatomy-critical final assets.
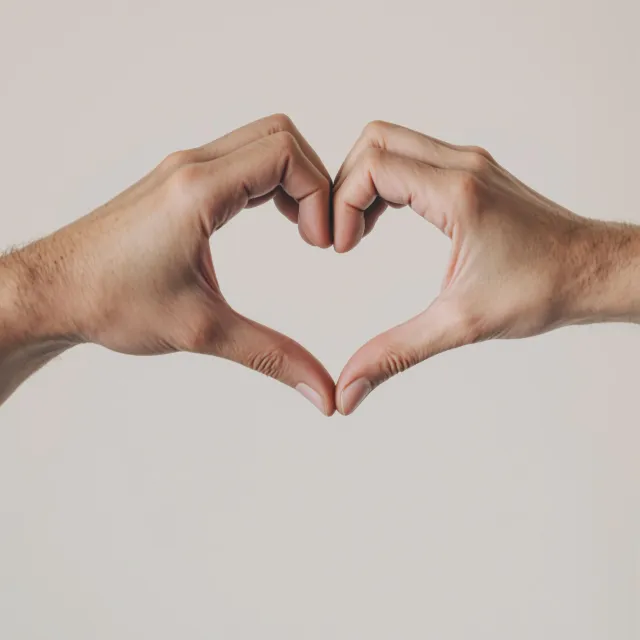
The hands forming a heart is the category's strongest result at 7/10, benefiting from readable geometry and convincing skin detail.
But the hand holding an apple scores 3/10 because the hand appears to have six digits. Other outputs show inflated fingers, strained proportions, or ambiguous contact.
For signing, instructional diagrams, sports technique, or close-up hand product photography, inspect digit count, joint structure, ownership, grip, and contact separately. A plausible hand is not sufficient evidence of a correct gesture.
7. Surreal products and imaginative transformations
Favor concepts with a concrete, recognizable silhouette.
The avocado armchair and mushroom-house forest both earn 8/10. Their central transformations remain visually explicit: furniture shaped like an avocado, and houses built on giant mushrooms.
More relational concepts are weaker. The musical-note skyline scores 3/10 because the two ideas are merely placed together. The glowing-book library also scores 3/10, replacing the requested book effects with lanterns.
Use the model for tangible fantasy-product exploration. Avoid relying on it to express symbolic relationships, recursion, or precise material substitutions without checking the result against the brief.
8. Architectural mood boards and interiors
Useful for atmosphere and massing; unsuitable as technical evidence.
The isometric Chinese temple complex earns 8/10, with readable levels, extensive ornament, and a consistent overall projection.
Technical and historical requests are less reliable:
Use these outputs for early visual direction. Do not use them to validate engineering, traditional joinery, room circulation, historical reconstruction, or buildable construction details.
9. Highly constrained and specialist requests
Avoid when correctness must be dependable on the first attempt.
In Ultra Hard, no result exceeds 6/10 overall despite generally strong rendering.
The horse riding an astronaut reverses the defining relationship. The robot self-portrait depicts the wrong subject on the canvas. The ASL thank-you portrait produces a stop-or-wave gesture instead of the requested sign.
These are substantial instruction failures, not minor finishing defects. Specialist communication, brand reproduction, exact historical hardware, and multi-part technical imagery require independent verification or controlled assembly.
10. Photorealistic portraits
Consider for idealized character imagery; avoid prioritizing it for naturalistic portrait fidelity.
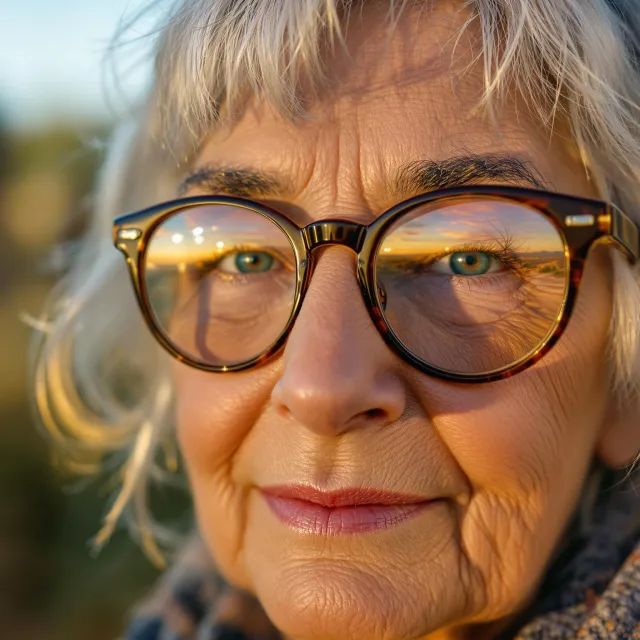
This is the weakest competitive category at 679 Elo. The elderly woman portrait is the strongest individual result at 7/10, but the requested bifocal segmentation is missing.
The heterochromia headshot renders amber rather than the specified green eye. The tearful bride delivers beauty styling without convincing tears. The toddler portrait looks doll-like rather than photographic.
These examples show why precise physical traits and subtle emotions need direct inspection, even when the face initially looks polished.
Recommended workflow
- Identify non-negotiables first: wording, counts, anatomy, roles, materials, and actions.
- Review meaning before finish: confirm that the requested event actually happens.
- Inspect at two scales: use a thumbnail for hierarchy and readability, then zoom in for anatomy, text, and structural connections.
- Finish externally where precision matters: replace typography, correct labels, rebuild vector assets, and validate patterns or technical details.
Bottom line: Flux 1.1 Pro Ultra is best treated as a polished concept generator with selective standout results—not as a dependable final-stage solution for exact visual instructions.