

Summary for Ultra Hard
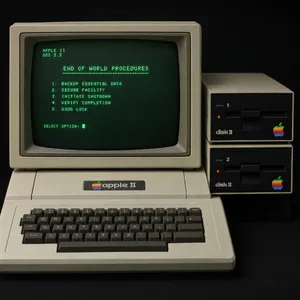
Welcome to the ultimate stress test for AI image generation! 🚀 The Ultra Hard category is specifically designed to push models to their absolute cognitive and rendering limits. These prompts test absurd spatial relationships, precise typography, retro UI replication, and cultural/anatomical accuracy.
Here are the key discoveries from our analysis:
- 🥇 Top Performers: Grok Imagine 2.0 dominates the category with an impressive 1439 Elo. It is closely followed by Takumi 1 (1420 Elo) and GPT Image 2.5 Sunburst (1394 Elo). These models excel because they possess deep semantic understanding, refusing to take the "easy way out" when given contradictory or complex instructions.
- 🧠 Intelligence over Beauty: A major trend is the triumph of prompt adherence over pure artistic polish. Models that usually top aesthetic charts, such as Midjourney v7 (975 Elo) and Midjourney V6.1 (767 Elo), struggled significantly here. When asked to draw a horse riding an astronaut, they defaulted to an astronaut riding a horse—resulting in severe penalties.
- 😲 Surprising Results: The ability of top models to handle dense, coherent mathematics is staggering. In the OpenAI Math Lecture prompt, top models successfully generated legible Bellman equations and cross-entropy formulas instead of random gibberish.
- 📌 Quick Takeaway: If your workflow requires precise instruction following, complex typography, or unusual spatial layouts, look to the latest generations of Grok, Takumi, and GPT Image.